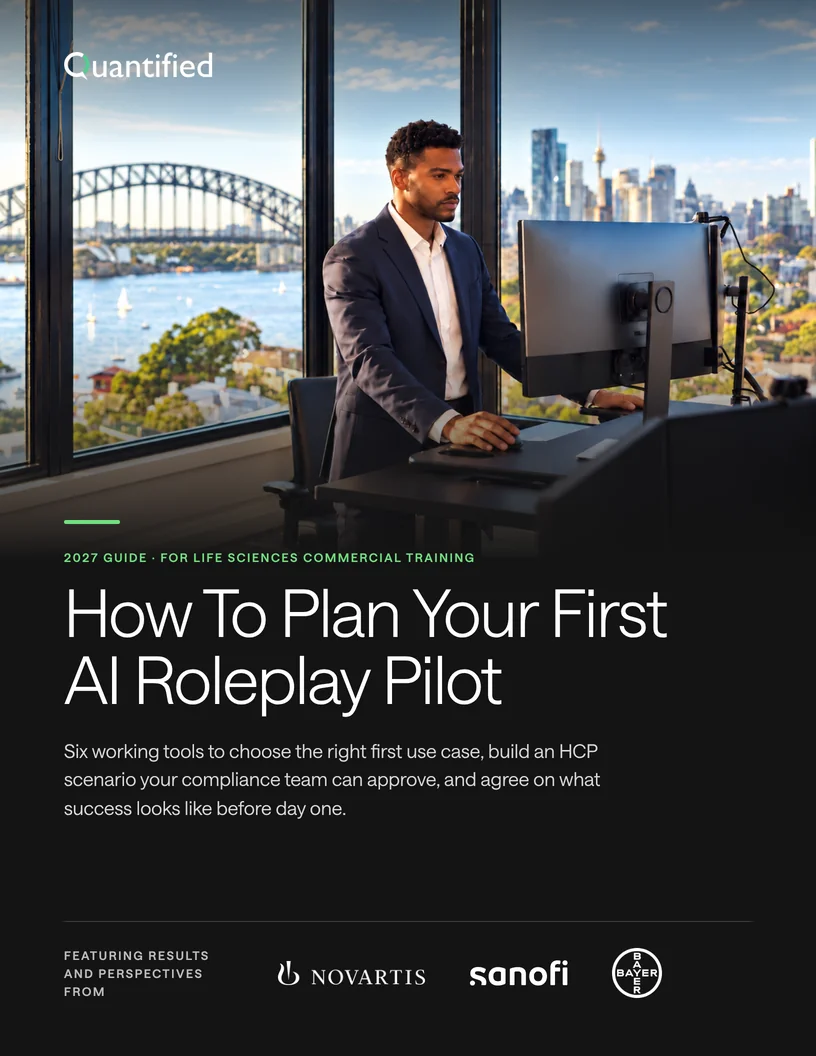
How To Plan Your First AI Roleplay Pilot
Download Now


An AI roleplay pilot should give your team clear evidence of what to do next. Before the first rep logs in, agree on the business priority, what readiness looks like, and how you’ll measure progress. That gives training and commercial leaders a shared basis for deciding whether and how to expand.
A pilot can generate positive feedback without answering whether the program is ready to scale. Agreeing on success criteria in advance helps avoid that uncertainty. This article focuses on how to build those criteria into the pilot so the results support both the training team’s recommendations and the sponsor’s investment decision.
This post sits between two we have already published. Running a compressed platform evaluation covers choosing a vendor on a deadline, and what four pharma L&D leaders learned scaling past the pilot covers what happens after a pilot succeeds. The vendor scorecard and week-by-week rollout plan live in our pilot guide, linked at the end.
Most stall for the same reason: they are bought as demos rather than aimed at a result. A realistic avatar impresses the room, the pilot starts with a loose goal like “see how reps respond,” and six weeks later the report shows logins, session counts, and a satisfaction survey. Those numbers describe adoption. They do not tell a commercial leader whether the field is more ready for a conversation that matters, and that is the question the budget depends on. Completion ≠ Readiness, and Satisfaction ≠ Readiness.
The pattern extends well beyond pharma. In McKinsey’s 2026 State of AI survey of 1,719 respondents, 44% said AI is scaling across their enterprise, up from 38% a year earlier, while 37% said AI has contributed positively to their organization’s EBIT. Adoption is widespread; measured value is harder to show. Pharma raises the bar further. Launch windows are short, label changes are frequent, and MLR review governs what reps are allowed to say. A pilot that cannot show readiness on an approved message, inside a real deadline, will struggle to earn a place in the next planning cycle.
A useful pilot connects practice to a business need. For a pharma training team, that might mean certifying a launch cohort within a shorter window, strengthening execution of an approved message, or reducing the trainer hours required for certification. Rep feedback helps explain the experience; readiness measures show what the team can do after practice.
Choose a result your commercial sponsor can use. If the priority is launch readiness, agree on the conversation reps need to handle, the criteria they must meet, and the date by which they need to demonstrate it. That makes the pilot easier to evaluate and gives the training team a concrete case to bring into planning discussions.
Participation and satisfaction are useful signals about adoption. Pair them with evidence of demonstrated skills, coaching actions, and the effort required to run the program. The table below shows how each measure can contribute to the decision.
Choose these measures before practice begins and record the starting point. A certification rate is more useful when the team can also explain the standard reps met, how they progressed, and what resources the program required.
Agree on these four decisions with the people who will run, review, and sponsor the pilot.
Pick a conversation the business already cares about: a product launch, a label update, a new indication, or a new-hire class. If the focus is objection handling, connect it to a specific conversation and business owner. A clear scope makes it easier to build relevant scenarios, support participation, and interpret the results.
The stakes make the deadline worth anchoring to. ZS analysis of 92 launches, published in June 2026, found that only 13% of brands met or exceeded expectations in each of their first three years. A pilot built around launch readiness answers a question the brand team is already asking.
Write down what a certified rep can do, not what they can recall. When Novartis Oncology faced a launch that moved up by roughly three months, the training team defined readiness as execution rather than knowledge. In the Novartis launch case study, Keenan Stare, Product and Disease Training Manager, put it this way: “Competency alone was not going to be enough to demonstrate readiness.” Scoring followed the four selling capabilities Novartis already coaches to, so the results fed straight into first-line coaching.
Score practice against your own approved criteria and exemplars. Training leaders and managers should share an understanding of what a passing score demonstrates and how they will use the results in coaching.
Decide what you are comparing against before practice begins. That might be the time it took to certify a comparable launch cohort in person, the trainer hours certification consumed, or first-attempt scores before practice. Note differences between cohorts or scenarios so the comparison stays useful. If reps already score highly at the start, efficiency or consistent performance may be more informative than score improvement alone.
A baseline is also what makes the result credible outside the training team. A Gartner survey of 227 chief sales officers, released in May 2026, found that 31% cited difficulty proving the ROI of AI-driven tools as a top challenge to their 2026 sales objectives. Gartner’s Sandhya Mahadevan put the fix plainly: “Having a reliable baseline is critical for validating where AI is improving existing performance.” Gartner also recommends “clear go or no-go criteria” when exploring new AI use cases, which is the next decision.
Agree with the sponsor on the evidence needed for each next step. Expansion might require a target share of reps to certify within the window, acceptable delivery effort, and managers using the results. An adjustment might be appropriate if readiness improves but scenario setup takes too long. Stopping may be appropriate if the pilot reveals a material requirement the solution cannot meet. Set the criteria before launch, and document any changes to scope or assumptions together.
Bring the following groups into planning so their requirements are reflected in the pilot and its evaluation.
The Novartis program shows the shape. Colleagues had already piloted AI roleplay, and three criteria decided the move to certification: flexibility to build scenarios for many stakeholders and business goals, objectivity in scoring every rep on the same criteria tied to the Novartis selling model, and efficiency in certifying on demand inside the window with a leader dashboard tracking every rep. The outcome was specific: 100% of the field force certified within the launch window, with 564 AI Roleplay sessions completed in about two days.
Other Quantified customer programs illustrate the kinds of outcomes a pilot can measure. Sanofi certified 100% of a 500-rep team in five days on a product launch with four trainers, with 80% certified within 48 hours. Bayer certified more than 500 reps with 4,500+ practice sessions logged and a 97% mastery rate. These examples provide useful measurement ideas; your own targets should reflect your cohort, starting point, and business requirements.
Review results against the criteria agreed before launch. Consider demonstrated readiness, adherence to approved messaging, manager use, and the effort required to repeat the program. Together, those measures help the team judge whether expansion is practical.
Quantified is the AI Sales Coaching Platform for life sciences and regulated commercial teams, built for regulated environments, not adapted from horizontal AI. In a pilot, scenarios are built from content your MLR team already approved, every session is scored against your MLR-cleared claims and on-label language, off-label language fails the scenario, and Compliance AI keeps an audit-ready record. General-purpose roleplay tools can score how a rep sounds; a regulated pilot also has to show that what the rep said was approved. Agree with your internal reviewers up front on the documentation they need, so the record answers their questions at review time instead of raising new ones.
Use these questions to guide the review:
If the agreed readiness and operational criteria are met, you have a basis for planning expansion. If results are mixed, identify the cause before choosing the next step. Flat scores might reflect a strong starting baseline, limited participation, a poorly matched scenario, or a genuine capability gap. An extension should test a specific explanation, with a defined change and review date. If the evidence shows the solution cannot meet a material requirement, stopping is a useful outcome too.
Use the pilot review to scope the next cohort, confirm the resources required, and assign ownership for scenario development and manager follow-through. Keep the readiness criteria visible as the program grows. Our guide to what AI sales coaching is for pharma commercial teams covers how practice, certification, and coaching fit together, and The L&D Leader’s Guide to Evaluating AI Sales Training for Pharma covers the criteria buying committees use when considering a purchase.
Long enough to cover one real readiness event and short enough to keep the deadline meaningful. Tie the length to the business event the pilot supports, such as a launch window or a new-hire class, rather than to a round number. Our pilot guide maps a six-week rollout as a starting point.
A proof of concept tests technical feasibility, often with a small internal group and sample content. A pilot evaluates use in your organization with real participants, relevant scenarios, and agreed success criteria. The questions you still need to answer should determine the scope of the evaluation.
Track certification against agreed criteria, performance relative to the baseline, on-label adherence, scenario setup and review time, and manager use of the results. Include participation and satisfaction to help explain adoption. Our post on measuring sales coaching effectiveness in pharma goes deeper.
Agree with your MLR team on the review required for scenarios, scoring, and pilot materials before launch. Starting with approved content gives reviewers a foundation, but it does not by itself establish that every scenario or output is approved.
A named executive sponsor, working with the training lead who runs the pilot. Together, they should agree on success criteria, review the evidence, and decide whether to expand, adjust, or stop.
Start with the readiness outcome your team needs to demonstrate. Our guide to planning your first AI roleplay pilot includes the decisions to make first, a weighted vendor scorecard, and a six-week rollout plan. To explore a pilot built around your own launch or certification priority, request a demo.